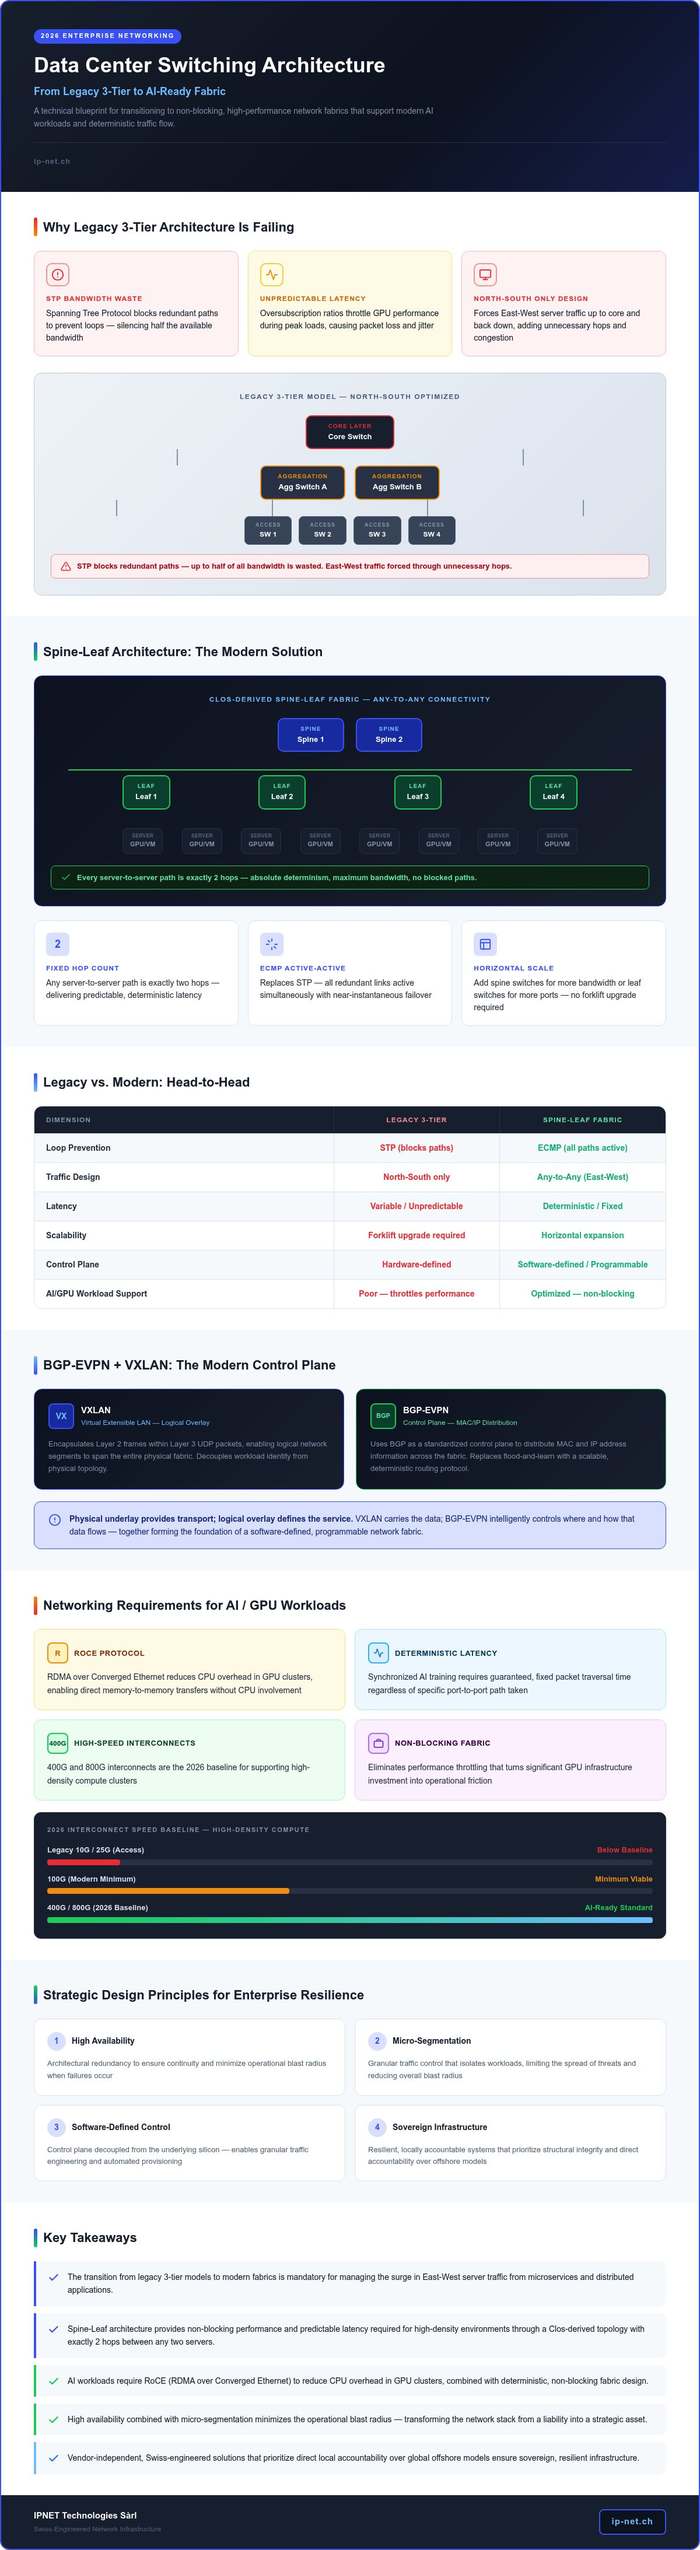
The traditional three-tier network is no longer a viable foundation for the modern enterprise; it’s a bottleneck that actively degrades high-performance compute clusters. As we move through 2026, the demands of AI workloads have exposed the inherent limitations of legacy data center switching architecture. You’ve likely seen how unpredictable latency and oversubscription ratios can throttle GPU performance, turning a significant infrastructure investment into a source of operational friction. We understand that maintaining stability while integrating disruptive technology requires more than just hardware upgrades. It demands a fundamental shift in how we engineer traffic flow.
This guide provides a technical blueprint for transitioning from rigid hierarchies to non-blocking, AI-ready fabrics. You’ll master the mechanics of Spine-Leaf designs and the implementation of BGP-EVPN VXLAN to ensure deterministic performance across your entire environment. We’ll examine how to build resilient, sovereign systems that prioritize structural integrity and local accountability. This ensures your networking stack remains a strategic asset rather than a liability in an increasingly complex digital landscape. By moving beyond legacy constraints, you can establish a network that supports both current operations and the future of automated intelligence.
Key Takeaways
- Understand why the transition from legacy 3-tier models to modern fabrics is mandatory for managing the surge in east-west server traffic.
- Discover how a Spine-Leaf data center switching architecture provides the non-blocking performance and predictable latency required for high-density environments.
- Identify the specific networking requirements for AI workloads; including the use of RoCE to reduce CPU overhead in GPU clusters.
- Establish a blueprint for enterprise resilience by implementing high availability and micro-segmentation to minimize operational blast radiuses.
- Master the advantages of vendor-independent, Swiss-engineered solutions that prioritize direct accountability over global offshore models.
Table of Contents
- Evolution of Data Center Switching: From Legacy 3-Tier to Modern Fabrics
- Spine-Leaf Architecture: Achieving Non-Blocking Performance
- Architecting for AI: GPU Clusters and Low-Latency Switching
- Strategic Design Principles for Enterprise Resilience
- Swiss-Engineered Excellence: The IPNET Advantage
Evolution of Data Center Switching: From Legacy 3-Tier to Modern Fabrics
For decades, the hierarchical three-tier model served as the gold standard for enterprise networking. This structure organized hardware into distinct Access, Aggregation, and Core layers; a design optimized for North-South traffic where data primarily flowed between external clients and internal servers. In this environment, the Spanning Tree Protocol (STP) acted as the primary mechanism for loop prevention. However, STP functions by intentionally blocking redundant paths, which effectively silences half of the available bandwidth. This waste of resources is no longer acceptable in a 2026 data center switching architecture where efficiency and throughput are paramount.
The fundamental nature of data movement has changed. Modern applications rely on distributed microservices and clustered databases that generate massive volumes of East-West traffic. This server-to-server communication bypasses the logic of hierarchical models, often forcing data to travel up to the core and back down again, creating unnecessary latency and congestion. To address this, the industry has shifted toward non-blocking fabrics that provide high-bandwidth, any-to-any connectivity.
The Decline of the Hierarchical Model
Legacy 3-tier architectures struggle with oversubscription ratios that throttle performance during peak loads. When too many servers at the Access layer compete for limited uplinks to the Aggregation layer, packet loss and jitter become inevitable. The rise of virtualization and containerized environments has exacerbated this issue, as workloads move dynamically across the physical footprint. This volatility demands a network that offers absolute determinism. In the context of modern switching, determinism is the guarantee that data packets will traverse the network with a fixed, predictable latency regardless of the specific port-to-port path taken. Without this predictability, synchronized AI training and high-frequency financial transactions fail to meet their performance benchmarks.
Defining the Modern Network Fabric
A modern network fabric replaces rigid hierarchies with a flatter, more agile topology. Modern architects favor the fat-tree network topology to eliminate the bottlenecks inherent in older designs, ensuring that every server is equidistant from every other server. This approach prioritizes three core characteristics: scalability, agility, and resilience. By 2026, the integration of 400G and 800G interconnects has become the baseline for supporting high-density compute clusters. We’ve moved beyond hardware-defined limitations toward software-defined switching, where the control plane is decoupled from the underlying silicon. This transition allows for granular traffic engineering and automated provisioning, transforming the data center switching architecture from a static utility into a dynamic, programmable asset that responds to real-time workload demands.
Spine-Leaf Architecture: Achieving Non-Blocking Performance
Every leaf switch in a spine-leaf topology connects directly to every spine switch, creating a high-performance fabric that eliminates the “choke points” of legacy designs. This ensures that any server-to-server path is exactly two hops away, delivering the absolute determinism required for modern workloads. By utilizing a data center switching architecture based on this Clos-derived topology, organizations eliminate the variable latency that plagues legacy systems. This physical layout provides a foundation where bandwidth is never sacrificed for loop prevention.
The most significant operational shift in this model is the total replacement of Spanning Tree Protocol (STP) with Equal-Cost Multi-Path (ECMP) routing. While STP deactivates redundant links to prevent loops, ECMP leverages every available connection simultaneously. This active-active load balancing maximizes total fabric bandwidth and provides near-instantaneous failover. Scalability becomes a matter of horizontal expansion. You can increase total bisectional bandwidth by adding spine switches or expand port density by adding leaf switches without disrupting existing traffic or requiring a complete forklift upgrade of the core.
BGP-EVPN and VXLAN: The Modern Control Plane
The physical underlay provides the transport, but the logical overlay defines the service. VXLAN (Virtual Extensible LAN) allows for the creation of Layer 2 virtual networks over a robust Layer 3 IP underlay, effectively extending the local network across the entire fabric without the limitations of traditional VLAN IDs. This encapsulation enables seamless workload mobility and multi-tenancy, allowing different business units or clients to coexist on the same physical hardware with complete isolation. To manage this complexity at scale, BGP-EVPN has emerged as the industry-standard control plane. It provides a unified method for discovering endpoints and distributing MAC and IP reachability information, which significantly reduces the reliance on inefficient flood-and-learn mechanisms that often plague larger environments.
Vendor-Independent Fabric Design
A resilient data center switching architecture must prioritize open standards to avoid the strategic risk of proprietary lock-in. While some manufacturers push closed ecosystems, a vendor-independent approach allows architects to select the best silicon for specific use cases, whether that involves Broadcom’s high-throughput ASICs or specialized programmable chips. This flexibility ensures that your infrastructure remains interoperable with both legacy hardware and future technological shifts. It places the power of architectural choice back into the hands of the enterprise.
When designing these complex environments, it’s essential to partner with experts who understand the nuances of Swiss-engineered reliability. Our team at IPNET Technologies Sàrl specializes in modern data center design that prioritizes structural integrity and long-term agility. We focus on outcome-oriented engineering that bridges the gap between current stability and future-ready performance.
Architecting for AI: GPU Clusters and Low-Latency Switching
AI training workloads, specifically those involving Large Language Models (LLMs), introduce traffic patterns that traditional networks simply weren’t built to handle. Unlike standard web traffic, AI data flows are massive, synchronized, and incredibly bursty. During the “All-Reduce” phase of model training, thousands of GPUs must exchange gradients simultaneously. If the data center switching architecture can’t facilitate this exchange with near-zero jitter, the entire compute cluster stalls. This synchronization makes the network the primary determinant of training efficiency; any delay in packet delivery translates directly into idle, expensive GPU cycles.
To mitigate these bottlenecks, modern architects implement Remote Direct Memory Access over Converged Ethernet (RoCEv2). This protocol allows GPUs to access each other’s memory directly without involving the host CPU, which significantly reduces latency and processing overhead. However, RoCEv2 requires a “lossless” environment. Since standard Ethernet is lossy by design, we must implement Priority Flow Control (PFC) and Explicit Congestion Notification (ECN). These mechanisms prevent buffer overflows by pausing specific traffic classes before drops occur, ensuring the integrity of the AI data stream. Optimizing buffer management is equally critical; switches must balance shared buffer pools to absorb the intense micro-bursts characteristic of AI collective communication.
GPU Interconnects vs. Traditional Switching
The debate between InfiniBand and Ethernet for AI infrastructure has intensified as we head into 2026. While InfiniBand was historically the default for high-performance computing due to its native lossless nature, the emergence of the Ultra Ethernet Consortium (UEC) has made high-speed Ethernet a formidable competitor. Tail latency represents the delay experienced by the slowest packets in a flow; in synchronized AI training, this “long tail” determines the overall completion time because the entire GPU cluster must wait for the slowest member to finish its collective communication step. Choosing the right data center switching architecture involves weighing the turnkey performance of InfiniBand against the flexibility and multi-vendor ecosystem of Ethernet-based fabrics.
MLOps Integration and Infrastructure Readiness
Preparing a switching fabric for AI isn’t just about hardware; it’s about integration with the broader MLOps platform. A truly AI-ready network requires deep observability to detect “incast” congestion before it impacts model convergence. We focus on scaling compute and network resources in tandem to prevent GPU starvation, where expensive accelerators sit idle waiting for data. By implementing automated telemetry and AIOps-driven management, Swiss enterprises can ensure their infrastructure remains resilient under the unique pressures of machine learning at scale. This proactive approach transforms the network from a potential bottleneck into a high-speed highway for innovation.
Strategic Design Principles for Enterprise Resilience
Resilience in a modern data center switching architecture requires a move away from simple device redundancy toward holistic system durability. High Availability (HA) must be integrated at every layer; this includes redundant power supplies, supervisor modules, and multi-homed server connections. We design for “Blast Radius” reduction by leveraging micro-segmentation within the VXLAN overlay. This approach ensures that a security breach or a technical failure in one segment remains isolated, preventing lateral movement across the fabric. This structural isolation serves as the physical manifestation of Zero Trust security. It treats every connection as potentially compromised until verified by the control plane.
Resilience Beyond Redundancy
True resilience extends to the operational lifecycle. Active-Active data center designs require a switching fabric that supports seamless traffic failover across geographically dispersed sites without manual intervention. We prioritize mechanisms like In-Service Software Upgrades (ISSU) to allow for critical firmware updates without incurring downtime. To manage this complexity, we integrate AIOps-driven managed services that utilize real-time telemetry to identify anomalies before they manifest as outages. This proactive stance moves the organization from reactive firefighting to a state of managed stability. It’s about building a guardian for current operations while architecting for future growth.
Network Automation and Orchestration
Manual configuration is a primary source of enterprise risk. Modern operations utilize Infrastructure as Code (IaC) to ensure that every switch deployment is consistent, repeatable, and documented. By adopting a NetDevOps mindset, teams can treat network configurations like software; they use version control and automated pipelines for testing. Automated validation ensures that any change to the data center switching architecture is verified against the intended state before it’s pushed to production. This rigorous process spans from Day 0 design to Day 2 operations, reducing human error and accelerating the deployment of new services. It transforms the network into a programmable, reliable asset.
For organizations seeking to modernize their core infrastructure, we provide expert Modern Data Center Design services that guarantee Swiss-engineered precision and direct accountability.
Swiss-Engineered Excellence: The IPNET Advantage
Modernizing a data center switching architecture requires more than just a procurement list of high-speed hardware. It demands a partner who understands the intersection of legacy stability and future-ready innovation. IPNET Technologies operates as a vendor-independent architect; we don’t answer to hardware manufacturers or follow proprietary agendas. Our focus remains solely on the structural integrity and performance outcomes of your specific environment. We prioritize Swiss accountability, ensuring that every design decision is backed by local expertise and a direct line of responsibility. We don’t utilize offshore hand-offs. Our engineers are rooted in the same regional precision that our clients expect from their mission-critical systems.
Our end-to-end service model bridges the gap between high-level strategy and granular execution. We guide enterprises through the entire lifecycle of their networking stack, from initial technical audits to 24/7 managed operations. By incorporating AI readiness into every layer of the architecture, we ensure that your infrastructure isn’t just surviving current demands but is actively prepared for the surge in GPU-intensive workloads. This commitment to engineering excellence transforms the network from a cost center into a resilient, strategic asset.
Vendor-Independent Technical Audits
An objective assessment is the mandatory first step in any modernization journey. We conduct deep-dive technical audits to identify the specific bottlenecks in your current data center switching architecture, whether they stem from oversubscribed uplinks or inefficient spanning-tree configurations. Our audit process includes:
- A comprehensive review of existing traffic patterns and latency benchmarks.
- Identification of hardware limitations that prevent the adoption of modern fabrics.
- The development of a strategic, phased roadmap for fabric migration.
- Risk-mitigation planning to ensure zero-downtime transitions.
This roadmap isn’t a generic template. It’s a customized engineering plan that respects your existing investments while providing a clear path toward a non-blocking, automated environment.
Managed AIOps and Operational Stability
Operational stability is the true measure of architectural success. Our managed services utilize AIOps to provide proactive monitoring and automated incident response, ensuring that your switching fabric maintains peak performance long after the initial deployment. We offer customized SLAs designed for mission-critical infrastructure, providing the peace of mind that comes with Swiss-based support. Our engineers act as a direct extension of your team, maintaining a constant vigil over your environment to prevent degradation before it impacts your business units. To begin your transition toward a more resilient network, schedule a vendor-independent infrastructure audit with our Swiss engineers. We’ll help you secure your current operations while building the foundation for your future AI initiatives.
Securing the Future of High-Performance Infrastructure
Modernizing your data center switching architecture isn’t merely a technical upgrade; it’s a strategic imperative for the AI era. We’ve explored the transition from legacy hierarchies to non-blocking spine-leaf fabrics, where determinism and predictable latency replace the bottlenecks of the past. For enterprises deploying GPU clusters, the shift toward lossless Ethernet and RoCEv2 is no longer optional. It’s the baseline for operational survival. You must prioritize structural integrity and micro-segmentation to ensure that your network remains a resilient foundation for innovation.
At IPNET Technologies, we bring 20 years of infrastructure expertise to every engagement. We provide unbiased, vendor-independent advisory services rooted in Swiss-engineered reliability. Our engineers ensure that your transition to an AI-ready environment is seamless, secure, and directly accountable. Don’t let legacy constraints stifle your growth. Consult with our Swiss-based architects for an AI-ready network design. We’re ready to help you build a network that’s as ambitious as your business goals.
Frequently Asked Questions
What is the difference between Spine-Leaf and traditional 3-tier architecture?
Spine-Leaf is a two-tier, non-blocking fabric designed for east-west traffic, whereas 3-tier is a hierarchical model optimized for north-south traffic. In a spine-leaf data center switching architecture, every leaf switch connects to every spine switch, ensuring equidistant paths and predictable latency. This eliminates the bottlenecks and spanning-tree limitations inherent in legacy hierarchical designs, providing the deterministic performance required for modern virtualized workloads and high-density compute clusters.
How does BGP-EVPN VXLAN improve data center scalability?
BGP-EVPN VXLAN decouples the logical overlay from the physical underlay, allowing for massive Layer 2 extension over a robust Layer 3 network. It uses BGP as a standards-based control plane to distribute reachability information, which effectively eliminates the inefficiency of traditional flood-and-learn mechanisms. This approach supports multi-tenancy and seamless workload mobility across thousands of endpoints. It provides a scalable framework that grows horizontally without the complex re-engineering required by legacy VLAN structures.
What are the specific switching requirements for AI and GPU clusters?
AI infrastructure requires high bisectional bandwidth, ultra-low latency, and zero packet loss. Because GPU clusters perform synchronized collective communication, any packet drop or jitter can cause GPU starvation and stall the entire training process. A robust data center switching architecture for AI must support 400G or 800G interconnects and implement lossless Ethernet protocols. These technical safeguards ensure that the network doesn’t become a bottleneck for expensive, high-performance compute resources.
Can I implement a modern switching fabric using multiple hardware vendors?
Yes, you can build a multi-vendor fabric by strictly adhering to open standards like BGP-EVPN and VXLAN. Vendor independence is a core strategic advantage that prevents proprietary lock-in and allows architects to select the best-of-breed hardware for specific performance tiers. Our engineering teams at IPNET specialize in designing these interoperable environments, ensuring that different silicon architectures communicate seamlessly. This approach provides long-term flexibility and better control over your infrastructure lifecycle.
What is RDMA over Converged Ethernet (RoCE) and why does it matter for AI?
RoCEv2 is a protocol that enables direct memory access between GPUs across an Ethernet network without involving the host CPU. This bypass significantly reduces latency and lowers CPU overhead, which is critical for the high-speed data exchanges required in AI training. However, RoCE requires a lossless environment to function correctly. This necessitates the implementation of Priority Flow Control (PFC) and Explicit Congestion Notification (ECN) within the fabric to prevent packet drops.
How does network automation reduce operational costs in the data center?
Network automation replaces error-prone manual configurations with Infrastructure as Code (IaC) and automated validation pipelines. By using a NetDevOps approach, enterprises can deploy consistent fabric configurations in minutes rather than days. This reduction in human error prevents costly outages and accelerates service delivery. Automation also simplifies Day 2 operations through real-time telemetry and AIOps, allowing smaller engineering teams to manage complex, high-density environments with significantly higher efficiency and reliability.
What are the security implications of a modern data center switching architecture?
Modern architectures improve security by reducing the blast radius through micro-segmentation and Zero Trust principles. By using VXLAN overlays, we can isolate workloads at a granular level, preventing lateral movement in the event of a breach. Security policies are decoupled from physical locations, ensuring consistent protection as workloads move across the fabric. This structural integrity, combined with deep observability, allows for faster threat detection and more effective containment compared to legacy models.
Leave a Reply